Flexible GraphRAG v0.8.0 released, with an optional CocoIndex integration

Flexible GraphRAG on GitHub

X.com Steve Reiner @stevereiner  LinkedIn Steve Reiner LinkedIn Posts

Repost of my LinkedIn post from August 20, 2026 (original LinkedIn post)
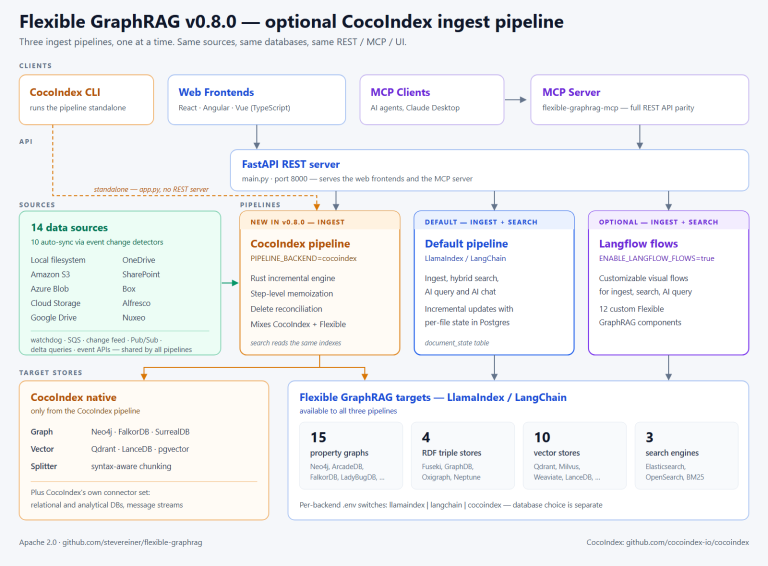
Flexible GraphRAG v0.8.0 released, with an optional CocoIndex integration. CocoIndex is a Rust based incremental sync and processing engine for context, agents, and data pipelines.
You can now use a CocoIndex pipeline working inside the Flexible GraphRAG app instead of the default pipeline.

Mixing components: CocoIndex components (source/target connectors, functions, splitting) and Flexible GraphRAG “Flexible” components: data sources, LlamaIndex / LangChain targets, document processing (LiteParse, Docling, LlamaParse), splitting, chunking, ontologies, KG extraction. These are separate from the Langflow “Flexible” components. In .env you pick a backend per piece (source, chunker, property graph, vector, search, KG extractor): llamaindex, langchain, or cocoindex; the database is configured separately. RDF is LangChain only, and KG extraction is LlamaIndex / LangChain, although the new custom KG extractors can use CocoIndex’s entity resolver.

Incremental updates: CocoIndex deals with incremental handling — step-level memoization, automatic delete reconciliation — instead of the Python based incremental update system. Postgres still keeps track of the data sources configured in the UI (datasource_config table), but the document_state table is not used. The event change detectors from the default system are also used with the CocoIndex pipeline for “Flexible” data sources: Alfresco ActiveMQ, Nuxeo Kafka, S3 SQS, Azure Blob change feed, GCS Pub/Sub, Google Drive Changes API, OneDrive/SharePoint MS Graph delta query, Box Events API, and Local Filesystem watchdog.

Outside the app too: this CocoIndex pipeline “app file” can be used outside the Flexible GraphRAG app for custom mixed apps. Also, CocoIndex provides CLI support.

Flexible GraphRAG components can be used : 14 data sources (10 auto syncing) and all the DBs — 15 property graphs, 4 RDF stores, 10 vector stores, 3 search engines. CocoIndex native components can be used too: vector DBs, property graph DBs, relational and analytical DBs, and message streams: https://cocoindex.io/docs/connectors/

A Flexible GraphRAG CocoIndex Integration Meeting Notes Knowledge Graph example is provided: any of 10 data sources, to any of 15 property graph databases.

Flexible GraphRAG is an Apache 2.0 open source AI context platform: document processing, knowledge graph auto-building, ontologies, many LLM providers, GraphRAG and RAG, hybrid semantic search, AI query, and AI chat. Python backend (LlamaIndex + LangChain), Angular / React / Vue frontends, an MCP server, Hyland Alfresco , Hyland Nuxeo support, and Docker Compose any database, dashboard.

GitHub: https://github.com/stevereiner/flexible-graphrag
Docs: https://stevereiner.github.io/flexible-graphrag/
PyPI: https://pypi.org/project/flexible-graphrag/
MCP PyPI: https://pypi.org/project/flexible-graphrag-mcp/
Docker: https://hub.docker.com/u/integratedsemantics
Blog: https://integratedsemantics.org/
CocoIndex: https://github.com/cocoindex-io/cocoindex
Flexible GraphRAG v0.7.1 is out: Visual Langflow integration, LiteParse support, and Microsoft Graph delta query (SharePoint, OneDrive)

Flexible GraphRAG on GitHub

X.com Steve Reiner @stevereiner  LinkedIn Steve Reiner LinkedIn Posts

Repost of my LinkedIn post from July 23, 2026 (original LinkedIn post)

Flexible GraphRAG v0.7.1 is out: Visual Langflow integration, LiteParse support, and Msft Graph delta query (SharePoint, OneDrive). v0.8.0, with optional CocoIndex support, is coming soon. Details in article:

Details

From my LinkedIn article (original article)

Flexible GraphRAG v0.7.1 released : Visual Langflow integration, added LiteParse support, and Microsoft Graph delta query (efficient incremental update for SharePoint, OneDrive). Also for v0.8.0, have optional initial support for CocoIndex coming soon.

Github: https://github.com/stevereiner/flexible-graphrag

1. Optional visual Langflow flows to customize the ingest pipeline and search flows used “under the covers” of the UI (OpenRAG like). Also have configurable “Flexible" Langflow components to use in other apps. Langflow+components can be used “standalone” running in a separate venv from the main Flexible GraphRAG backend venv, or with a new docker with the flexible components, available on https://hub.docker.com/u/integratedsemantics (along with the previous optional dockers for backend, react, vue, and angular frontends)

2. A Previous post mentioned that if Langflow mode is enabled, incremental updating will also flow thru the customizable pipeline. Now all 13 data sources will flow thru it and some fixes were made. App UI , MCP, and REST all will use the visual flows when the ENABLE_LANGFLOW_FLOWS is true.

3. Added support for the open source LiteParse from LlamaIndex in addition to previous support for Docling and LlamaParse (LiteParse can be configured to send to other parsers for a list of complexity reasons) LiteParse github https://github.com/run-llama/liteparse

4. Added support for Microsoft delta query for efficient incremental change updating for SharePoint and OneDrive data sources.

5. For v0.8.0 (not checked in) have an optional CocoIndex pipeline working inside the Flexible GraphRAG app. CocoIndex github https://github.com/cocoindex-io/cocoindex This pipeline supports mixing CocoIndex things and "Flexible LlamaIndex / LangChain things” from Flexible GraphRAG. Things = connectors (sources, targets), functions ( document processor supporting Docling, LlamaParse, and Liteparse, chunking / splitting, and KG extraction). These are separate from the Langflow “Flexible” components. With this pipeline, CocoIndex deals with incremental handling instead of the existing Flexible GraphRAG Python based incremental update system with Postgres for state management. Still can use it to keep track of multiple datasource_configs, setup in the app UI, and optional monitoring logging.
6. This CocoIndex pipeline app can be used outside of the Flexible GraphRAG app for custom mixed apps.

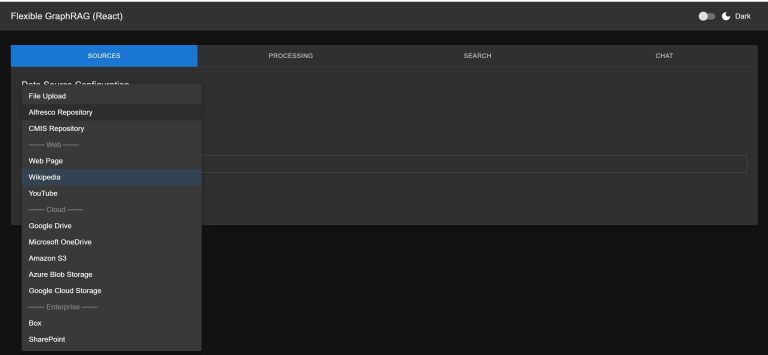
7. Thus Flexible GraphRAG things can be used : 13 data sources (9 auto syncing with Alfresco ActiveMQ, S3 SQS, Azure change feed, GCS pub/sub, MS Graph delta query, watchdog filesystem change detectors), DBs: 15 property graphs, 4 RDF stores, 10 vector stores, 3 search engines) in addition to CocoIndex "native" things. In the .env config, for each backend ( source, property graph , search, vector, chunker/spitter) in framework config section, you can setup to use llamaindex, langchain or cocoindex. RDF is langchain only, KG extraction is currently only llamaindex or langchain. What particular database to use is separately configured.

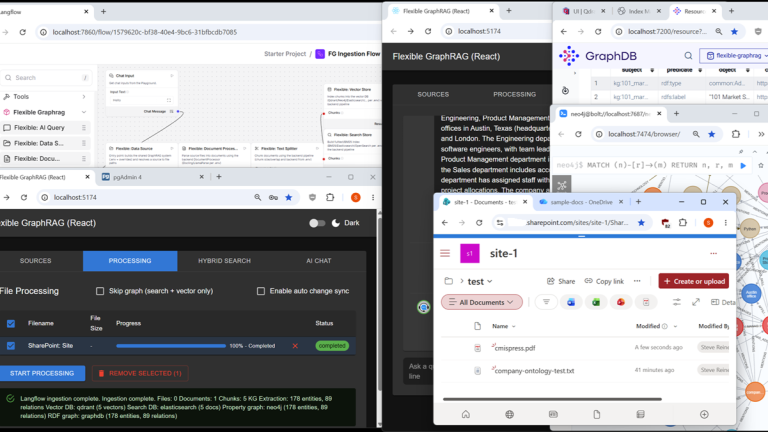
8. Screenshot shows Flexible GraphRAG running in Langflow pipeline mode, with an auto sync data source setup with SharePoint (using MS delta query), PDF file was parsed by LiteParse, with Qdrant vector, Elastic search, Neo4j property graph, and Graphwise Ontotext GraphDB RDF graph all getting initial sync, add, delete, modify changes. Flexible GraphRAG processing tab shows initial sync status, chat is being used to ask “Who works for Acme” and “How is Acme organized” using context in all 4 dbs from the ingestion of company-ontology-test.txt (Flexible GraphRAG was setup in ontology mode with 3 ttl turtle files)

Flexible GraphRAG v0.6.0 released: Full LangChain support in addition to LlamaIndex, 15 graph, 4 RDF, 10 vector, 3 search databases

Flexible GraphRAG on GitHub

X.com Steve Reiner @stevereiner  LinkedIn Steve Reiner LinkedIn Posts

Repost of my LinkedIn post from May 15, 2026 (original LinkedIn post)

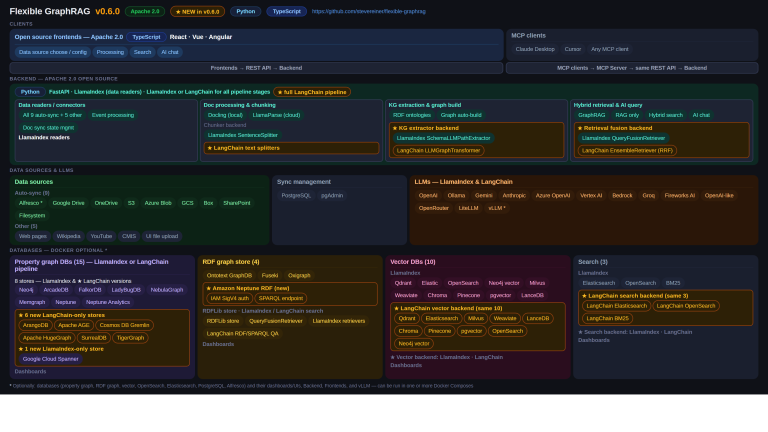
Flexible GraphRAG v0.6.0 released: Full LangChain support in addition to LlamaIndex, more DBs: 15 graph (8 + Arango, Apache AGE, Microsoft Azure Cosmos for Gremlin, SurrealDB, Google Cloud Spanner, HugeGraph, TigerGraph), 4 RDF (3 + Amazon Neptune RDF), 10 vector, 3 search.

GitHub repo: https://github.com/stevereiner/flexible-graphrag

Flexible GraphRAG is an Apache 2.0 open source AI context platform supporting a document processing pipeline (Docling or LlamaParse), knowledge graph auto-building, ontologies, schemas, many LLM providers, GraphRAG and RAG, hybrid semantic search (fulltext, vector, property graph, RDF/SPARQL), AI query, and AI chat. The backend is Python. Angular, React, and Vue TypeScript frontends and an MCP server are included. The stack supports 13 data sources (9 with incremental auto-sync), 15 property graph databases, 4 RDF triple stores , 10 vector databases, OpenSearch / Elasticsearch / BM25 search, and Alfresco.

Goals for added Flexibility with Frameworks and Pipelines:
1. More Databases
2.a. Framework Independence (with adapter layer)
2.b. support both LangChain and LlamaIndex python application / agent developers (will need python apis not just current REST and MCP).
3. Flexible pipelines: custom python for stages and pipelines
4. Support OpenRAG or OpenRAG like with customizable visual Langflow
flows for the pipeline and retrieval flows.
5. Support the CocoIndex rust pipeline and incremental engine as option to current flexible graphrag incremental update system (python/postgres). Also Flexible GraphRAG data sources and property graph, rdf, vector, search dbs could be used with CocoIndex as custom connectors (in addition native and other custom CocoIndex connectors). Flexible GraphRAG’s React, Vue, and Angular frontends would provide UI.

What's new:
• Full LlamaIndex, LangChain or mixed pipeline: chunker, KG extractor, graph/vector/search backends, retrieval fusion — each independently configurable
• 15 property graph DBs (8 LI stores + 8 LangChain matching versions + 6 LC-only + 1 new LI) All 15 can be used in a LlamaIndex or LangChain focused pipeline
• 4 RDF stores — now includes Amazon Neptune RDF
• 10 LangChain vector backends + 3 LangChain search backends duplicate LlamaIndex support
• LangChain EnsembleRetriever (RRF) + text-to Cypher / GQL / SurrealQL / AQL / SPARQL graph QA
• Docling OCR support (RapidOCR, EasyOCR, Tesseract, and more)
• Incremental add/delete/modify across all graph, vector, search, and RDF backends (for both LlamaIndex and LangChain backend stores)
• Integration testing: run_matrix and run_overnight can test all databases, LI / LC pipeline stages, all LLM providers, and all embedding providers

Update, v0.6.1 (May 16, 2026): Updated to v0.6.1 to fix packaging missing adapter files. The issue happened when installing from PyPI, not when using a GitHub source clone. The latest on PyPI is now 0.6.1 for both the main backend: https://pypi.org/project/flexible-graphrag/ and the MCP server: https://pypi.org/project/flexible-graphrag-mcp/

Flexible GraphRAG and RAG: LlamaParse from LlamaIndex and Docling now both working for doc processing with Box, Google Drive, GCS, Azure Blob, S3

Flexible GraphRAG on GitHub

X.com Steve Reiner @stevereiner  LinkedIn Steve Reiner LinkedIn Posts

Repost of my LinkedIn post from November 10, 2025 (original LinkedIn post)

Flexible GraphRAG and RAG checkin: LlamaParse from LlamaIndex
and Docling now both working for doc processing with Box, Google Drive, GCS, Azure Blob, S3, File Upload, Hyland Alfresco, and CMIS data sources.
Please 🌟 Star the GitHub repo
https://github.com/stevereiner/flexible-graphrag

1. LlamaParse added as an additional configurable doc processing choice beyond Docling (default).
2. Newly working Box, Google Drive, GCS, Azure Blob Storage data sources work with both Docling and LlamaParse.
3. Previous data sources that worked with Docling now also working with LlamaParse: File Upload, Hyland Alfresco, CMIS, S3
4. Currently working to get SharePoint and OneDrive for Business to test.
5. The web data sources (Web Pages, Wikipedia, YouTube) don’t use document processing

Flexible GraphRAG or Flexible RAG, an Apache 2.0 open source python platform, uses LlamaIndex, supports 8 graph databases, 10 vector databases, 3 search engines, and 13 data sources, Also supports knowledge graph auto-building, schemas, LlamaIndex LLMs, Docling and LlamaParse doc processing, GraphRAG mode, RAG only mode, Hybrid search, and AI query / chat. Has React, Vue, and Angular frontends, and a FastAPI backend. React, Vue, Angular, Backend work on Windows, Mac, Linux (standalone or in docker). Also has a FastMCP MCP server. Has a convenient docker compose that can include any of the databases (Vector, Graph, Search, Alfresco) and Dashboards / Consoles.

Flexible GraphRAG or RAG is flexing to the max: 8 Graph databases, 10 Vector databases, 3 search engines working (can docker compose all including dashboards), 13 data sources

Flexible GraphRAG on GitHub

X.com Steve Reiner @stevereiner  LinkedIn Steve Reiner LinkedIn Posts

Flexible GraphRAG or Flexible RAG, an Apache 2.0 open source python platform, is now flexing to the max using LlamaIndex, in terms of supporting more databases and data sources: supports 8 graph databases, 10 vector databases, 3 search engines, and 13 data sources,. Also supports knowledge graph auto-building, schemas, LlamaIndex LLMs, Docling doc processing (LlamaParse coming soon), GraphRAG mode, RAG only mode, Hybrid search, and AI query / chat. Has React, Vue, and Angular frontends, and a FastAPI backend. React, Vue, Angular, Backend now work on Windows, Mac, Linux (standalone or in docker). Also has a FastMCP MCP server. Has a convenient docker compose that can include any of the databases (Vector, Graph, Search, Alfresco) and Dashboards / Consoles.

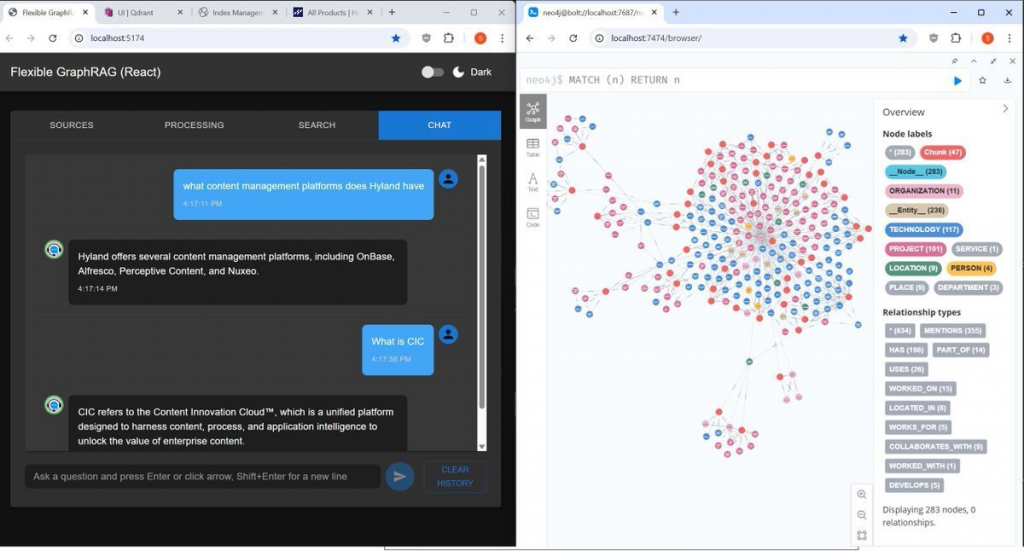
(Flexible GraphRAG AI chat shown with Hyland products web page(s) used with web pages data source to auto-generated a Neo4j graph).

Convenient docker compose: you can choose to include from all supported 10 vector and 8 graph databases, Elasticsearch, OpenSearch, and Hyland Alfresco Community. Include in the docker-compose.yaml by just removing the # comment in front of their includes. Dashboards / Consoles for these databases, as much as possible are also included in the docker compose choices (either in the yaml file for the database or for some a separate yaml file include).

You can run the docker with the databases with the backend and frontends (React, Angular, Vue) running stand alone in separate terminal windows. In addition to running the databases in docker, you can include the backend and frontends in the dock compose by including the app-stack.yaml and proxy.yaml includes. Now have no config duplication for standalone backend+frontends vs full docker mode: previously had to repeat all config in app-stack.yaml now use env_file: include standalone backend .env and overrides with include of docker.env (for configs that need host.docker.internal)

All 8 Graph database working: Neo4j, ArcadeDB, FalkorDB, archived Kuzu (LadybugDB fork todo), NebulaGraph, Memgraph, Amazon Neptune, Amazon Neptune Analytics

All 10 Vector databases working: Qdrant, Elasticsearch vector, OpenSearch vector, Neo4j vector, Milvus, Weaviate, Chroma (both http, embedded), Pinecone, PostgreSQL + pgvector, LanceDB

All 3 Search engines working: Elasticsearch, OpenSearch, LlamaIndex built-in BM25

New Data Sources: using LlamaIndex readers: 1. working ones that don’t use document processing: Web Pages, Wikipedia, Youtube, 2. working using document processing: S3, 3. ones using document processing still to test: Google Drive, Microsoft OneDrive, Azure Blob, GCS, Box, SharePoint.

Support for Docling document processing is currently available. Being able configure to use LlamaParse coming soon.

Original data sources with document processing that don’t use LlamaIndex readers: filesystem, Alfresco, CMIS. Hyland Alfresco Community can be included in the docker compose by taking the “#” comment off the beginning of its include.

LLMs: LlamaIndex LLMs (LlamaIndex has support for very many), Flexible GraphRAG currently has config for 1. tested, working: OpenAI, Ollama, 2. untested: Anthropic Claude, Google Gemini, Azure OpenAI.

Previous Flexible GraphRAG posts:

See Flexible GraphRAG Initial Version Blog Post

See New Tabbed UI for Flexible GraphRAG (and Flexible RAG)

See Flexible GraphRAG: Performance improvements, FalkorDB graph database support added

See Flexible GraphRAG: Supports ArcadeDB Graph Database with new LlamaIndex Integration

See Flexible GraphRAG: Amazon Neptune, Neptune Analytics, and Graph Explorer support added