X.com Steve Reiner @stevereiner LinkedIn Steve Reiner LinkedIn Posts
Repost of my LinkedIn post from July 23, 2026 (original LinkedIn post)
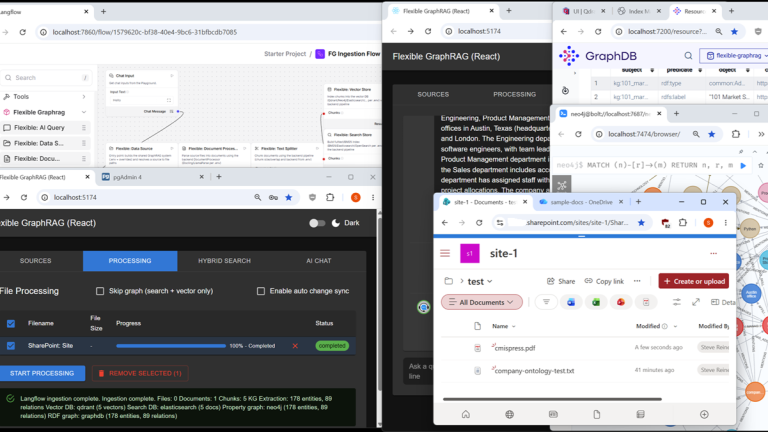
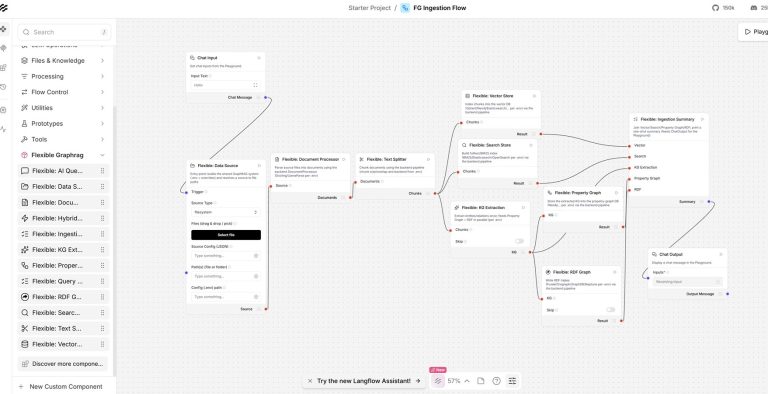
Flexible GraphRAG v0.7.1 is out: Visual Langflow integration, LiteParse support, and Msft Graph delta query (SharePoint, OneDrive). v0.8.0, with optional CocoIndex support, is coming soon. Details in article:
Details
From my LinkedIn article (original article)
Flexible GraphRAG v0.7.1 released : Visual Langflow integration, added LiteParse support, and Microsoft Graph delta query (efficient incremental update for SharePoint, OneDrive). Also for v0.8.0, have optional initial support for CocoIndex coming soon.
Github: https://github.com/stevereiner/flexible-graphrag
1. Optional visual Langflow flows to customize the ingest pipeline and search flows used “under the covers” of the UI (OpenRAG like). Also have configurable “Flexible" Langflow components to use in other apps. Langflow+components can be used “standalone” running in a separate venv from the main Flexible GraphRAG backend venv, or with a new docker with the flexible components, available on https://hub.docker.com/u/integratedsemantics (along with the previous optional dockers for backend, react, vue, and angular frontends)
2. A Previous post mentioned that if Langflow mode is enabled, incremental updating will also flow thru the customizable pipeline. Now all 13 data sources will flow thru it and some fixes were made. App UI , MCP, and REST all will use the visual flows when the ENABLE_LANGFLOW_FLOWS is true.
3. Added support for the open source LiteParse from LlamaIndex in addition to previous support for Docling and LlamaParse (LiteParse can be configured to send to other parsers for a list of complexity reasons) LiteParse github https://github.com/run-llama/liteparse
4. Added support for Microsoft delta query for efficient incremental change updating for SharePoint and OneDrive data sources.
5. For v0.8.0 (not checked in) have an optional CocoIndex pipeline working inside the Flexible GraphRAG app. CocoIndex github https://github.com/cocoindex-io/cocoindex This pipeline supports mixing CocoIndex things and "Flexible LlamaIndex / LangChain things” from Flexible GraphRAG. Things = connectors (sources, targets), functions ( document processor supporting Docling, LlamaParse, and Liteparse, chunking / splitting, and KG extraction). These are separate from the Langflow “Flexible” components. With this pipeline, CocoIndex deals with incremental handling instead of the existing Flexible GraphRAG Python based incremental update system with Postgres for state management. Still can use it to keep track of multiple datasource_configs, setup in the app UI, and optional monitoring logging.
6. This CocoIndex pipeline app can be used outside of the Flexible GraphRAG app for custom mixed apps.
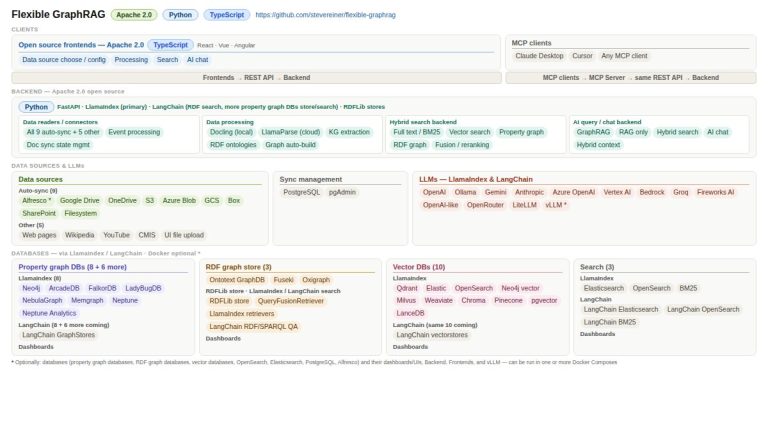
7. Thus Flexible GraphRAG things can be used : 13 data sources (9 auto syncing with Alfresco ActiveMQ, S3 SQS, Azure change feed, GCS pub/sub, MS Graph delta query, watchdog filesystem change detectors), DBs: 15 property graphs, 4 RDF stores, 10 vector stores, 3 search engines) in addition to CocoIndex "native" things. In the .env config, for each backend ( source, property graph , search, vector, chunker/spitter) in framework config section, you can setup to use llamaindex, langchain or cocoindex. RDF is langchain only, KG extraction is currently only llamaindex or langchain. What particular database to use is separately configured.
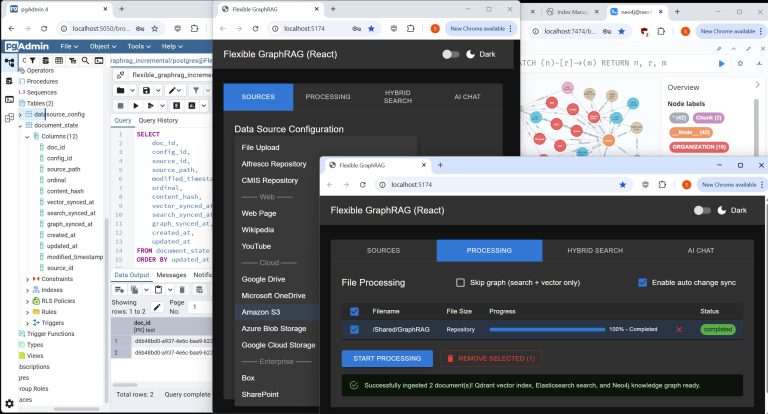
8. Screenshot shows Flexible GraphRAG running in Langflow pipeline mode, with an auto sync data source setup with SharePoint (using MS delta query), PDF file was parsed by LiteParse, with Qdrant vector, Elastic search, Neo4j property graph, and Graphwise Ontotext GraphDB RDF graph all getting initial sync, add, delete, modify changes. Flexible GraphRAG processing tab shows initial sync status, chat is being used to ask “Who works for Acme” and “How is Acme organized” using context in all 4 dbs from the ingestion of company-ontology-test.txt (Flexible GraphRAG was setup in ontology mode with 3 ttl turtle files)